With the rapid development of new software for large language models self-hosting and local LLM inference, support for AMD graphics cards is becoming increasingly widespread. Here is a list of the most popular LLM software compatible with both NVIDIA and AMD GPUs, along with additional information you might find useful if you’re just starting out. I will do my best to update this list frequently, so that it continues to be a useful and reliable resource for as long as possible. Last article update: October 2026.
If you’re looking for the very best AMD graphics cards you can get for local AI inference using the LLM software presented on this list, I’ve already put together a neat resource for picking up the very best GPU model for your needs. Feel free to take a look!
Also, if you want to get into AI image generation too, you can check out my full list and comparison of the most popular Stable Diffusion WebUI software here.
Base Windows/Linux Requirements For AMD GPU Compatibility – ROCm
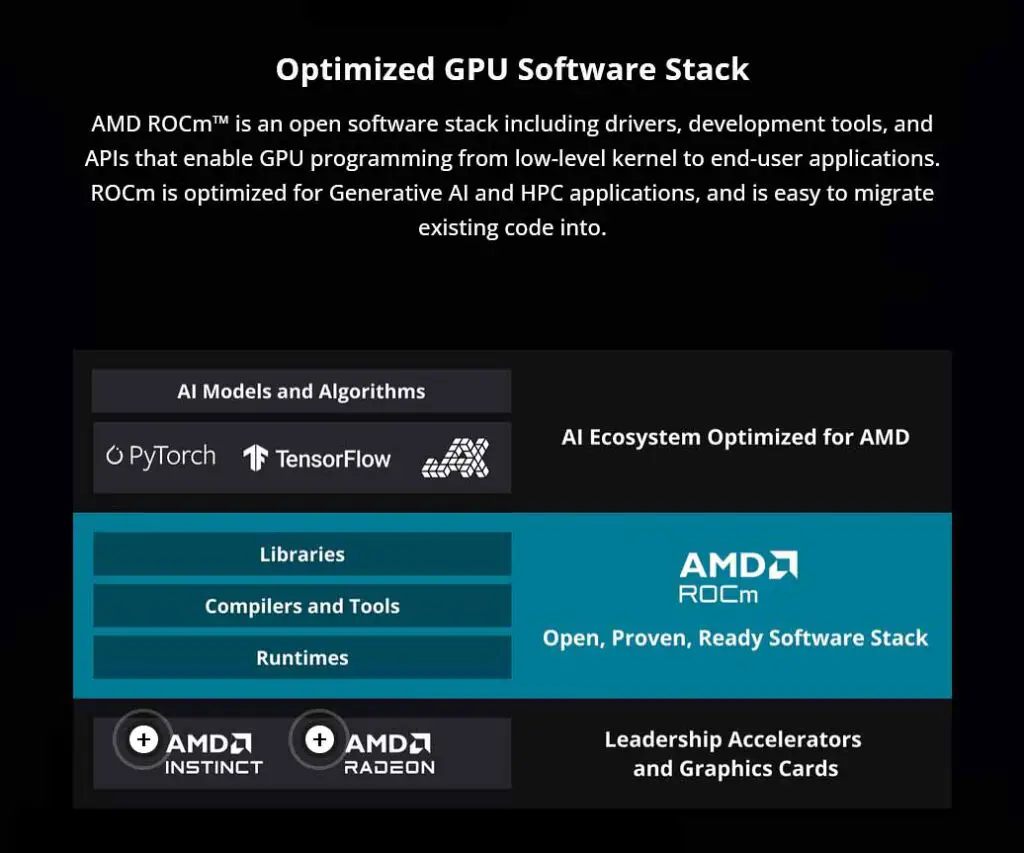
The AMD ROCm software stack, which is still in active development, is one of the things you’ll need if you want to efficiently run your large language models using a new AMD graphics card.
One of the key components for leveraging AMD graphics cards most efficiently (especially the newest models), regardless of your operating system, is ROCm. It’s an open-source software stack for GPU-accelerated computing, and it works in a similar way to the closed-source CUDA from NVIDIA.
As of October 2026, ROCm is finally a proper cross-platform solution. While historically ROCm releases for Windows have lagged behind their Linux counterparts, the latest ROCm release (10.1.0, October 2026) officially supports both Linux and Windows 11 for the Radeon RX 9000 and RX 7000 series cards, as well as Ryzen AI processors, allowing you to run AI workloads directly on AMD hardware in a Windows environment.
For now, full ROCm support is still most robust for the newest AMD graphics cards. While on Linux you can often enable support for officially unsupported AMD GPUs (like some in the Radeon RX 6000 series) by modifying the HSA_OVERRIDE_GFX_VERSION environment variable, this is not as straightforward on Windows.
On Windows, you used to need the separate AMD HIP SDK to get ROCm. AMD now treats the HIP SDK (last released as version 7.2.0) as legacy, and the current ROCm install guide has you install ROCm on Windows from Python pip packages or a tarball instead, on top of an up-to-date AMD Software: Adrenalin Edition driver. On Linux, you can use the official package manager setup or install scripts from the AMD ROCm website. Keep in mind that some of the programs listed below, like LM Studio, the TextGen portable builds and Unsloth Studio, come with or download their own ROCm libraries, so you won’t always have to install ROCm by hand.
If installing or using ROCm isn’t an option, most of the software on this list also supports the Vulkan graphics API or the OpenCL framework. While generally slower than ROCm, these will still allow you to use your AMD GPU for model inference.
Unsupported AMD GPUs – HSA_OVERRIDE_GFX_VERSION
As mentioned, if you have an older AMD GPU that doesn’t officially support ROCm, you might still be able to benefit from ROCm GPU acceleration on Linux. Modifying the HSA_OVERRIDE_GFX_VERSION parameter can override the Graphics Core Next (GCN) version that the ROCm libraries utilize, which can enable certain features on unsupported hardware.
Again, keep in mind that for now, modifying this variable is primarily a solution for Linux systems.
LLM Software Full Compatibility List – NVIDIA & AMD GPUs
Here is the full list of the most popular local LLM software that currently works with both NVIDIA and AMD GPUs. Note that some programs might require a bit of tinkering to get working with your AMD graphics card. Refer to the table below and use the project links to check out further details on the official websites and repositories for the listed software. All of the listed programs support ROCm and Vulkan, unless stated otherwise.
Swipe the table sideways to see all columns.
| Software | Interface | Platforms | AMD GPU Support | Docker | Links |
|---|---|---|---|---|---|
| LM Studio | Desktop app | Windows macOS1 Linux | ROCm, Vulkan | No | Project Site |
| Unsloth Studiobeta | WebUI | Windows macOS Linux | ROCmRX 6000 and newer | Yes | Project SiteGitHub Page |
| Gpt4All | Desktop app | Windows macOS Linux | Vulkan | No | Project SiteGitHub Page |
| KoboldCPP | WebUI | Windows macOS1 Linux | Vulkan, ROCmROCm via a separate fork | Yes | GitHub (Main)GitHub (ROCm) |
| MLC LLM | CLI & API | Windows macOS Linux Android* iOS* | ROCm, Vulkan | No | Project SiteGitHub Page |
| Llama.cpp | Built-in WebUI | Windows macOS Linux | ROCm, Vulkan | Yes | GitHub Page |
| Ollama | Desktop appWindows & macOS | Windows macOS Linux | ROCm, VulkanROCm on Windows: RX 7000 and newer | Yes | Project SiteGitHub Page |
| AnythingLLM | Desktop app | Windows macOS Linux Android* | YesThrough its built-in Ollama engine | Yes | Project SiteGitHub Page |
| Oobabooga TextGenformerly Text Generation WebUI | WebUI & desktop app | Windows macOS Linux | ROCm, Vulkan | Yes | GitHub Page |
| Jan | Desktop app | Windows macOS Linux | Vulkan, ROCmROCm: Linux only, experimental | No | Project SiteGitHub Page |
| Llamafile(s) | WebUI | Windows macOS Linux BSD | ROCm, Vulkan | No** | Project SiteGitHub Page |
1Apple Silicon Macs only.
*Android and iOS are listed only if the software features an official Android/iOS application. Some of the programs here (for instance Llama.cpp and Ollama), can, with some additional effort be run on Android devices, for instance by utilizing Termux.
**You can easily containerize Llamafiles using the following method.
If you want to know which one of these you should choose if you have no prior experience with this kind of software, or are simply curious about the installation process for each and want more details, the next section of this article should help with that. Aside from that, this is another resource that may just interest you: Beginner’s Guide To Local LLMs – How To Get Started
So, Which One of These Is The Easiest to Set Up & Install?
Below is a quick summary of all the software from the table above with additional comments, mainly focusing on the simplicity of the installation process. This information will be updated alongside the table above.
- LM Studio – Extremely easy to set up for both AMD and NVIDIA users, making it one of the best options for beginners. It features one-click installers for Windows, macOS (Apple Silicon only), and Linux, and for AMD cards you can switch between its Vulkan and ROCm runtimes right in the app. Note that unlike the other software on this list, it is closed source. In July 2026, the LM Studio team also released LM Studio Bionic, a new, separate AI agent app for coding, research and document work that runs local models through the same LM Studio runtime. It doesn’t replace LM Studio, which is still available and gets regular updates.
- Unsloth Studio – A newer, open-source no-code web UI (still in beta) from the team behind the popular Unsloth fine-tuning library, which lets you both run and train models locally, with GGUF model chat working 100% offline. It installs with a single command:
curl -fsSL https://unsloth.ai/install.sh | shon macOS, Linux and WSL, orirm https://unsloth.ai/install.ps1 | iexin Windows PowerShell, and there is also an official Docker image (unsloth/unsloth). Chat works even without a GPU, and on AMD graphics cards it installs ROCm for you, with Radeon RX 6000 series and newer cards supported on both Windows and Linux. You can learn more about it on the official Unsloth Studio page. - Gpt4All – Similar to LM Studio, it offers simple installers for Windows, MacOS, and Linux. It also has broad GPU support through Vulkan. Keep in mind that it hasn’t had a new release since version 3.10.0 in February 2025, so it may lag behind the other options here when it comes to support for the newest models.
- KoboldCPP – Comes as a single ready-to-run executable for Windows, Linux, and macOS. AMD users should start with the Vulkan option in the main release, and if you want ROCm, there is a separate ROCm compatible fork, which usually lags a few versions behind the main project. I’ve also prepared a full setup guide for it here: Quickest SillyTavern x KoboldCpp Starter Guide (Local AI Characters RP)
- MLC LLM – Can be easily installed on your system using Python pip with a single console command on Windows, macOS, and Linux, with prebuilt packages for both ROCm and Vulkan. Installing it in an isolated conda virtual environment is highly recommended. Native Android and iOS mobile apps are a strong point for this software.
- Llama.cpp – Pre-compiled binaries are available for Windows, Linux, and macOS, including Vulkan builds for Windows and Linux, and ROCm builds for Linux. You can also install it with winget on Windows, or brew and nix on macOS and Linux. It now also comes with a built-in WebUI for chatting with your models.
- Ollama – Simple installers are available for Windows and macOS, with an installation script for Linux, and the Windows and macOS apps now also include a simple chat window. It has an official list of supported AMD cards, and AMD cards that aren’t on that list can still use the Vulkan backend.
- AnythingLLM – For Windows and MacOS, AnythingLLM has a one-click installer that should automatically download the necessary dependencies for GPU acceleration. A simple installation script is available for Linux. Its built-in local model provider uses the Ollama engine under the hood, and there is also an official Android app.
- Oobabooga TextGen (formerly Oobabooga Text Generation WebUI) – In 2026 the project was renamed to TextGen and turned into a desktop app. You can now simply download one of its portable builds, unzip it and launch it, with ready-made ROCm and Vulkan versions for both Windows and Linux, so AMD users no longer have to go through the extra manual setup steps older versions required.
- Jan – Installers are available for Windows, macOS, and Linux. AMD GPUs use the Vulkan backend, and GPU acceleration can be enabled in the software settings (Settings > Hardware > GPUs). Since version 0.8.2 (June 2026), Jan also offers an experimental ROCm backend for AMD cards, but only on Linux.
- Llamafile – Llamafiles are designed to be used right away after downloading and typically do not require any additional setup. The project is now maintained by Mozilla.ai, and on Windows, a single llamafile can’t be larger than 4GB, so bigger models need to be loaded as separate GGUF files.
Are NVIDIA Cards any Better When It Comes To Local LLMs?
The reality is that while AMD is catching up in AI software compatibility, particularly due to the slower development of ROCm compared to NVIDIA’s CUDA technology, many of their newer GPU models are more than capable for most tasks related to hosting large language models locally.
When using AMD graphics cards with compatible LLM software, you might occasionally encounter a more complex setup process and slightly slower inference speeds. However, these issues are likely to become less significant as the ROCm framework continues to evolve.
Currently, AMD graphics cards (and lately also the Intel Arc GPUs) are often more affordable than those from NVIDIA, especially when considering the price per 1GB of VRAM, a crucial factor for hosting larger, higher-quality language models.
Taking all this into account, I can safely say this: AMD cards are becoming increasingly reliable for handling various AI-related tasks. Their lower price point, even for the latest models, makes them a worthwhile option for many users.
If you can accept the possibility of a more involved software configuration in some rare cases, as well as potential software incompatibility with older cards, then sticking with or choosing Radeon cards for your new LLM hosting setup can be a very reasonable idea. Let’s keep our fingers crossed for AMD in the near future.
You might also like: Intel Arc B580 & A770 For Local AI Software – A Closer Look